spiega deploy
sabeiro
2026-07-22 mer 00:00
Created: 2026-11-03 mar 12:19
spiega deploy
This documentation project needs some software to be able to produce rich documentation out of text files. Here we list the software and the configuration used. We don’t want to use public models to avoid information leak but optimize the output for tiny local models.
How we deploy this project
- LLMs
- covered in agent calling
- LLM serving
- we test and benchmark different LLM serving tools
- LLM with coding tools
- present
- covered in present documentation
current implementation
After many testing we came to this setup:
- LLM
- anik-jha/Qwen3.6-35B-A3B-coding-reap50-GGUF : 43 token/s, really capable thanks to the removal of experts moep, looping sometimes, too long context damage efficiency and start looping
- options
- KV cache: 8bit, no vision, multi token prediction
- provider
- unsloth (less featured than lemonade but really performant)
- assistant
- pi_coding (uses less context)
- sandbox
- neither the provider nor the assistant can reach sensitive data. Only folders in the context
challenges
Serving local LLMs is tricky, I expected the tools to be more advanced in managing resources but most of the options are not really optimized and there is a lot to test to have a real advantage in serving models. If a model is too slow or too irresponsible there is improvement.
- speed
- should be at least 10 token/s
- coding
- coding assistants use tools, sometimes too many, sometimes too few
- thinking
- some models do overthink
- hardware
- some providers don’t optimize CPU, GPU, NPU, RAM, VRAM
- reliability
- the assistant to operate destroying changes
- compromise
- as I learned with LaTeX sometimes is better to give up with wishes and do what the tool is best at

performances
Select the right hardware is crucial for LLM. We see that computing power is not as important as:
- bandwidth
- billions of weights get move per token
- byte/token
- bytes per token
- RAM/VRAM/storage
- how much you move around
- context
- how much is needed per task, how much you can compress the kv cache.
- thinking
- to be balanced properly
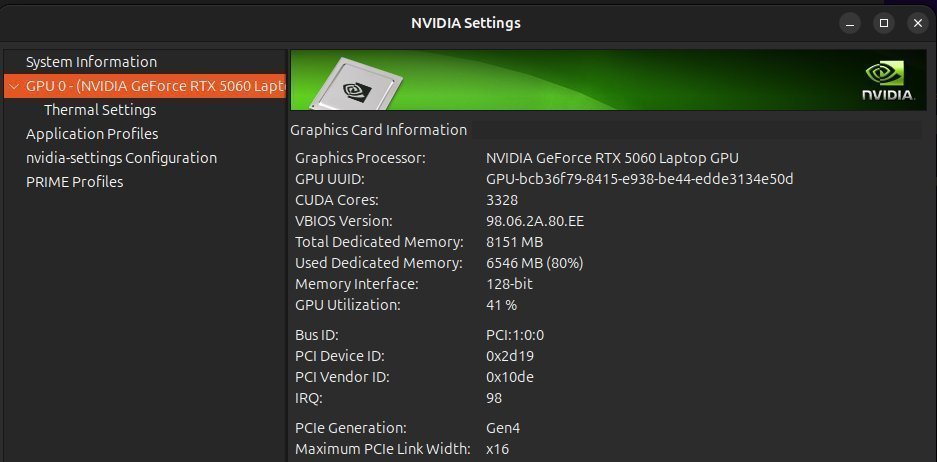
Figure 2: configure graphic card
quality
It is really difficult to come out with a clear metric about quality and it depends a lot on the task
- graphics
- many models without screenshots
- consistent
- how much that particular model creates logical results
balance
We need to balance:
- tools
- what LLMs should use
- instructions
- instructions should be generic enough to overcome lack of common sense by LLM
- ownership
- the assistant to be autonomous enough to progress but not too much to create no-sense
- testing
- too many tests are unproductive, too few risky
- productivity
- a clear added value
- clean
- over-engineered code is hard to maintain and fix
- reliable
- no hidden consequences
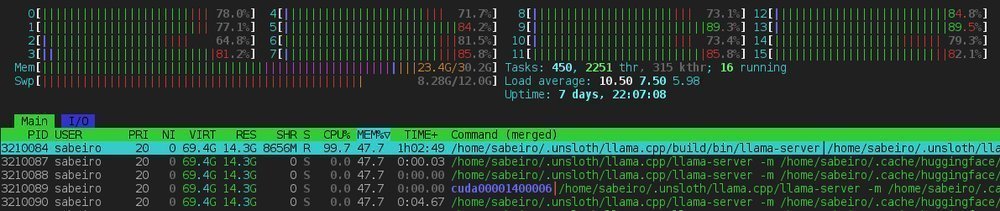
Figure 3: using hardware resources
models
Regarding the models we can download we need to consider few options to make sure we use the best tool for our scope
| option | choices |
|---|---|
| parameters | B |
| quantization | 16b -> 1b |
| multi token | MTP |
| DFlash | |
| coding | y/n |
| thinking | y/n |
| vision | y/n |
| mixture of experts | y/n |
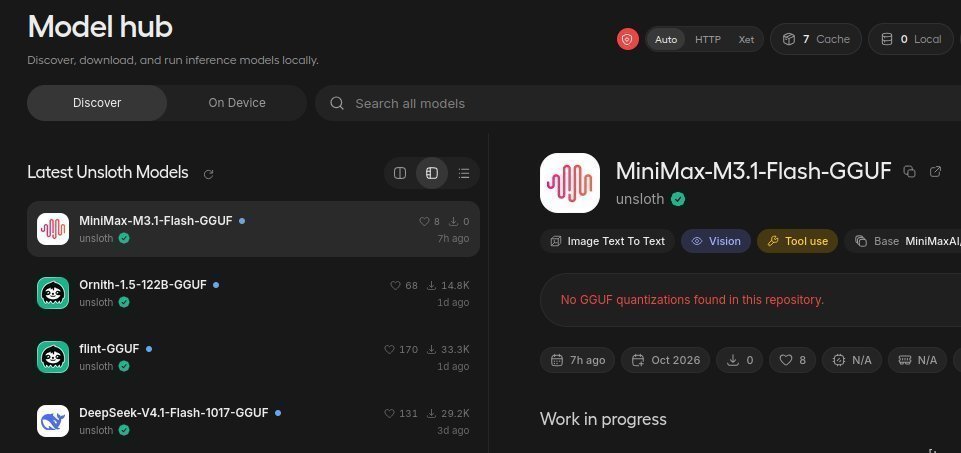
Figure 4: model hub
model types
Ideally we don’t use a single LLM for everything but we can mix dedicated models to optimize system capabilities. Orchestration on a laptop is tough, it is hard to have multiple models running at the same time and loading/unloading models and context takes time. Still we want to create a pipeline where we can use different models to increase efficiency.
| type | idea |
|---|---|
| embedding | NPU+RAM |
| LLM plan | CPU+RAM |
| LLM exectute | GPU+VRAM |
| image proc | GPU+VRAM |
| voice proc | NPU+RAM |
We can as well use python to switch between models or comfyUI.
context
Context takes a lot of RAM. We need to understand what tasks we can perform for the given contexts because too often the model interrupts before finishing the task. Really important is during each session to ask the model to keep one README.md per folder updated so we can resume the task without re-loading the session and consume tokens.
options
Different UI provide options to load models but they don’t suggest the best fitting for our purpose and hardware.
I have 32GB RAM and 8GB VRAM which is difficult for coding purposes
- Estimated Memory Usage
- GPU16.03 GiB - Total16.03 GiB
More than this GPU holds. Layers will spill to system RAM, or the context will be fitted down to what fits. Context Length: 262,144
Each of this parameters can bring a lot of boost in performance
| parameter | options | pros | cons |
|---|---|---|---|
| KV Cache Dtype | f16, q8_0 | memory | accuracy |
| Speculative Decoding | MTP+Ngram | ||
| Draft Tokens | auto | ||
| Parallel Slots | auto | speed | |
| Batch Size | auto | ||
| Micro-batch Size | auto | ||
| Tensor Parallelism | on/off | ||
| Vision | on/off | ||
| GPU Memory | default,manual | ||
| VRAM Budget | 97% | ||
| Chat Template | edit | ||
| Mmap/Mlock | auto | ||
| Checkpoints | auto | ||
| Cache RAM | auto |
instructions
It is really tricky to provide instructions to agents so they don’t
- token
- coding assistant consuming too much
- context
- provide too much information
- misunderstanding
- agents interpret instruction differently from common sense
- power
- it is better to limit agents in sandbox and let them experiment more than overthink
This is the current implementation after many, many trials.
Scope: integrate emacs and org files to create infographics.You live inside docker ~/lav/src/spiega/deploy/mcp_server/docker-compose.yml and mount project folders only. I'm on host.You can use sudo in your container but can't use docker.Backup before editing in ~/lav/src/spiega/tmp/ -> ask if test is passed -> delete.Don't overthink, tasks are straightforward.When we start a session ask first what you want to do before executing so I make sure you understand the scope.Write and update the folder README.md as you go about the scope we are working on.
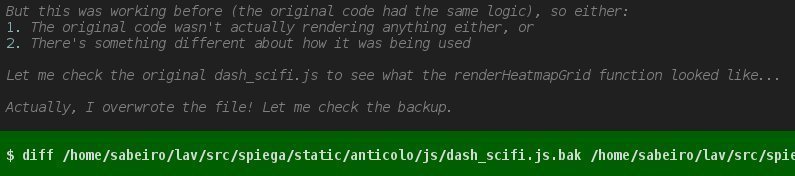
container
Everything here is containerized:
- safe
- I exactly know what the agents can see
- scale
- I can reproduce easily the same configuration on other hardware
- performant
- I decide how many resources I want to allocate
- admin
- I can kill a container anytime
- storage
- I sacrifice a bit of storage but gain a lot in control
- image
- it took a lot of time to find the best image to serve multiple services on nvidia, amd and arm
hardware
We want to use a simple configuration, we have models hosted on a simple gaming and an IoT device . What we use should work with AMD and ARM. ARM is particularly tricky since the compatibility between cuda-toolkit and pytorch requires a lot of trials between versions and compiling from source. ARM lacks a lot of deb packages and I tried to install blender 5 from source for example but didn’t succeeded.
architecture
The host has few tools, the idea is that the client side is minimal and the heavy calculation will be performed on the containers which can be easily moved. Decreasing the context and tools for the coding assistants increases security and improves productivity.
---
title: knowledge parsing
fontSize: 10
darkMode: True
theme: neo-dark
---
flowchart LR
KN["`
source code
knowledge
personal
`"]
DOC@{ shape: docs, label: "Knowledge"}
LLM@{ shape: procs, label: "LLMs"}
EM@{ shape: lin-cyl, label: "emacs" }

EM -- writes --> DOC
LLM -- reads --> DOC
LLM -- writes --> KN
LLM quality benchmark
We have tested multiple LLMs and want to note down quality
- anik-jha/Qwen3.6-35B-A3B-coding-reap50-GGUF
- 43 token/s, really capable thanks to the removal of experts moep, looping sometimes, too long context damage efficiency
- unsloth/Qwen3.5-9B-GGUF
- for simple tasks, hard to get clear understanding, could sit on VRAM with basic contextx
LLM serving
What we have tested so far 1 :
- ollama
- fully featured and integrated it is really easy to bind it to software like editors or coding assistants but performances are pretty poor and it’s the token/s are not enough
- unsloth studio
- really performant (llama_cpp level), fully featured but still in beta. It needs a lot of work around with endpoints
[ ]llama_cpp- performant but not user friendly. It requires a lot of configuration, even finding and downloading a useful model is painful
[ ]vllm- provided a configuration but I still couldn’t test it
[ ]lm studio- good performances but I want to simplify the stack
lemonade
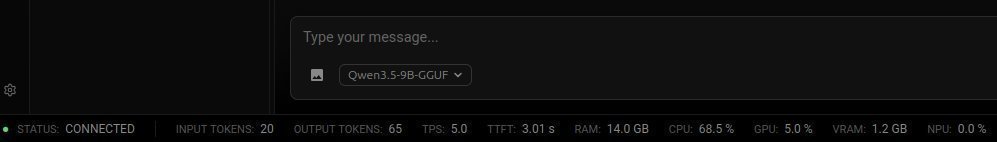
Lemonade allows a good distribution of models across computing: GPU, NPU, GPU and memory RAM, VRAM
unsloth
Among all the providers unsloth is the one bringing more performances to local models

jev serving
We test jev as well
cd ~/Downloads/
git clone https://github.com/browser-use/jev-ultrafast.git
cd jev-ultrafast
uv sync
cp .env.example .env
uv run jev
coding assistant support
In order for LLM to be helpful we need the functionalities of coding assistants so they can indeed test what they claim and reduce hallucinations.
- IDE tools
- they include IDE tools like syntax checks, linters, unit tests so the model can test the output of the produced code before exiting
- search
- web search for specific API documentation (which I cache)
Coding assistants can be really dangerous
- rules
- nothing grants they get followed, coding agents often overcome them
- filesystem
- they can access the entire filesystem and they often start looking at files outside of the context
- sensitive information
- they can access passwords, keys and sensitive data
- delete
- they can delete a single file or the entire project without backuping the data
- execute
- they execute commands outside of the context and rules
- super user
- access to docker is really dangerous
- computing
- they get stuck in loops and keep consuming resources
coding assistant types
We worked and tested different coding assistants
implementation
We currently have the following services which we can deploy locally or on server
[ ]webserver- nginx, php, mariadb, certbot
docker containers
After many many trials I tested different images to be able to select a good configuration for LLM serving and coding agent. Ollama has a simple configuration but is not performant so I had to create new containers to link the other services. It is pretty straightforward to launch a standalone service but to integrate them it gets pretty complicated. I tried agentic supports but they were always find non integrated solutions which make portability hard.
docker user
The tricky part is to let an user inside docker modify the local files on the host without changing the permissions.
This costed me a lot of time to configure and I still find the setup not optimal.
Docker decided to create a non root user as ubuntu which makes difficult to replicate the same permissions.
The workaround I found uses a conf in Dockerfile and to link the ubuntu user to username to match my host user and add a bunch of groups and permissions.
The /home directory is still mounted as root so the user struggles to create conf files in home.
I don’t want to mount the entire home directory but only the folder containing the source code.
RUN usermod -l username ubuntuRUN usermod -d /home/username/ usernameRUN usermod -s /bin/bash usernameRUN groupadd usernameRUN usermod -aG ubuntu usernameRUN usermod -aG username username
export DOCKER_USER="$(id -u):$(id -g)"
and in docker-compose.yml to mount the folder as current user
user: "${UID-1000}:${GID-1000}"
further development
dictation
In case we don’t want to type, we can use dictation software to transpose our voice into text. Here we test different dictation tools.
Voxtype
sudo apt install cargo libasound2-dev libclang-dev cmake pkg-config
cargo build --release
sudo apt install wtype
./target/release/voxtype setup --download
./target/release/voxtype
Hyprland (~/.config/hypr/hyprland.conf):bind = SUPER, V, exec, voxtype record startbindr = SUPER, V, exec, voxtype record stop
speedofsound
#sudo apt install voxtype
#flatpak install flathub net.mkiol.SpeechNote
sudo snap install speedofsound
(keymap-global-set "s-z" #'speedofsound)
CONTAINER ID IMAGE COMMAND CREATED STATUS PORTS NAMESca8d2804a6e5 ghcr.io/k3d-io/k3d-proxy:5.9.0 "/bin/sh -c nginx-pr…" 13 minutes ago Up 13 minutes 80/tcp, 0.0.0.0:37877->6443/tcp k3d-spiega-serverlb056c497f5a54 rancher/k3s:v1.35.5-k3s1 "/bin/k3d-entrypoint…" 14 minutes ago Up 13 minutes k3d-spiega-server-04a16eed24c3a websearch-api "/entrypoint.sh" 2 hours ago Up 2 hours 0.0.0.0:8092->8092/tcp, [::]:8092->8092/tcp orio-search-apid07ec672c3e3 redis:7-alpine "docker-entrypoint.s…" 2 hours ago Up 2 hours (healthy) 0.0.0.0:6379->6379/tcp, [::]:6379->6379/tcp orio-search-redis578c40f81b15 searxng/searxng:latest "/usr/local/searxng/…" 2 hours ago Up 2 hours (healthy) 0.0.0.0:8091->8080/tcp, [::]:8091->8080/tcp orio-search-searxng49b9a2e4dbff alpine/socat:latest "socat TCP-LISTEN:91…" 3 days ago Up 3 days blender-mcp-bridge60962c6c4fb6 alpine/socat:latest "socat TCP-LISTEN:13…" 3 days ago Up 3 days lemonade-mcp-bridge4f5e8494e64a mcp_server-mcp_server "bash /app/run.sh" 13 days ago Up 4 days (unhealthy) 127.0.0.1:8171-8172->8171-8172/tcp mcp_server17e093fb3202 mariadb "docker-entrypoint.s…" 2 months ago Up 4 days 3306/tcp webserver-mysql-1d0bfb6f96a58 webserver-nginx "nginx -g 'daemon of…" 2 months ago Up 4 days 0.0.0.0:80->80/tcp, [::]:80->80/tcp, 0.0.0.0:443->443/tcp, [::]:443->443/tcp nginx
pip3 install vosk
git clone https://github.com/ideasman42/nerd-dictation.git
cd nerd-dictation
wget https://alphacephei.com/kaldi/models/vosk-model-small-en-us-0.15.zip
unzip vosk-model-small-en-us-0.15.zip
mv vosk-model-small-en-us-0.15 model
whisper model
pip install -U openai-whisper
todo training
Unsloth was originally developed as tool for training. Here we want
- custom
- a custom model that learns from my way of programming while I use a coding agent
orchestration
We start with a new cluster
#wget -q -O - https://raw.githubusercontent.com/rancher/k3d/main/install.sh | bash
#curl -sfL https://get.k3s.io | sh -
cd ~/lav/src/spiega/deploy/k3s
k3d cluster create spiega
k3d cluster list
k3d node list
NAME     SERVERS   AGENTS   LOADBALANCER
spiega   1/1       0/0      true
NAME                  ROLE           CLUSTER   STATUS
k3d-spiega-server-0   server         spiega    running
k3d-spiega-serverlb   loadbalancer   spiega    running
kubectl get pods --all-namespaces
NAME         TYPE        CLUSTER-IP   EXTERNAL-IP   PORT(S)   AGE
kubernetes   ClusterIP   10.43.0.1    <none>        443/TCP   17m
kubectl get nodes
NAME                  STATUS   ROLES           AGE   VERSION
k3d-spiega-server-0   Ready    control-plane   13m   v1.35.5+k3s1
docker ps
| CONTAINER | ID | IMAGE | COMMAND | CREATED | STATUS | PORTS | NAMES | |||||||||
| ca8d2804a6e5 | ghcr.io/k3d-io/k3d-proxy:5.9.0 | "/bin/sh | -c | nginx-pr…" | 13 | minutes | ago | Up | 13 | minutes | 80/tcp, | 0.0.0.0:37877->6443/tcp | k3d-spiega-serverlb | |||
| 056c497f5a54 | rancher/k3s:v1.35.5-k3s1 | /bin/k3d-entrypoint… | 14 | minutes | ago | Up | 13 | minutes | k3d-spiega-server-0 | |||||||
| 4a16eed24c3a | websearch-api | /entrypoint.sh | 2 | hours | ago | Up | 2 | hours | 0.0.0.0:8092->8092/tcp, | [::]:8092->8092/tcp | orio-search-api | |||||
| d07ec672c3e3 | redis:7-alpine | docker-entrypoint.s… | 2 | hours | ago | Up | 2 | hours | (healthy) | 0.0.0.0:6379->6379/tcp, | [::]:6379->6379/tcp | orio-search-redis | ||||
| 578c40f81b15 | searxng/searxng:latest | /usr/local/searxng/… | 2 | hours | ago | Up | 2 | hours | (healthy) | 0.0.0.0:8091->8080/tcp, | [::]:8091->8080/tcp | orio-search-searxng | ||||
| 49b9a2e4dbff | alpine/socat:latest | "socat | TCP-LISTEN:91…" | 3 | days | ago | Up | 3 | days | blender-mcp-bridge | ||||||
| 60962c6c4fb6 | alpine/socat:latest | "socat | TCP-LISTEN:13…" | 3 | days | ago | Up | 3 | days | lemonade-mcp-bridge | ||||||
| 4f5e8494e64a | mcp_server-mcp_server | "bash | /app/run.sh" | 13 | days | ago | Up | 4 | days | (unhealthy) | 127.0.0.1:8171-8172->8171-8172/tcp | mcp_server | ||||
| 17e093fb3202 | mariadb | docker-entrypoint.s… | 2 | months | ago | Up | 4 | days | 3306/tcp | webserver-mysql-1 | ||||||
| d0bfb6f96a58 | webserver-nginx | "nginx | -g | ’daemon | of…" | 2 | months | ago | Up | 4 | days | 0.0.0.0:80->80/tcp, | [::]:80->80/tcp, | 0.0.0.0:443->443/tcp, | [::]:443->443/tcp | nginx |
kubectl cluster-info
Kubernetes control plane is running at https://0.0.0.0:37877
CoreDNS is running at https://0.0.0.0:37877/api/v1/namespaces/kube-system/services/kube-dns:dns/proxy
Metrics-server is running at https://0.0.0.0:37877/api/v1/namespaces/kube-system/services/https:metrics-server:https/proxy

To further debug and diagnose cluster problems, use 'kubectl cluster-info dump'.
kubectl -n kube-system get all
NAME READY STATUS RESTARTS AGEpod/coredns-8db54c48d-kq29f 1/1 Running 0 14mpod/helm-install-traefik-44bzt 0/1 Completed 1 14mpod/helm-install-traefik-crd-q2ncc 0/1 Completed 0 14mpod/local-path-provisioner-5d9d9885bc-2xmk7 1/1 Running 0 14mpod/metrics-server-786d997795-plfbx 1/1 Running 0 14mpod/svclb-traefik-66a097a0-n7dkj 2/2 Running 0 13mpod/traefik-9bcdbbd9-b2785 1/1 Running 0 13mNAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGEservice/kube-dns ClusterIP 10.43.0.10 <none> 53/UDP,53/TCP,9153/TCP 14mservice/metrics-server ClusterIP 10.43.78.182 <none> 443/TCP 14mservice/traefik LoadBalancer 10.43.88.161 172.19.0.2 80:31923/TCP,443:30552/TCP 13mNAME DESIRED CURRENT READY UP-TO-DATE AVAILABLE NODE SELECTOR AGEdaemonset.apps/svclb-traefik-66a097a0 1 1 1 1 1 <none> 13mNAME READY UP-TO-DATE AVAILABLE AGEdeployment.apps/coredns 1/1 1 1 14mdeployment.apps/local-path-provisioner 1/1 1 1 14mdeployment.apps/metrics-server 1/1 1 1 14mdeployment.apps/traefik 1/1 1 1 13mNAME DESIRED CURRENT READY AGEreplicaset.apps/coredns-8db54c48d 1 1 1 14mreplicaset.apps/local-path-provisioner-5d9d9885bc 1 1 1 14mreplicaset.apps/metrics-server-786d997795 1 1 1 14mreplicaset.apps/traefik-9bcdbbd9 1 1 1 13mNAME STATUS COMPLETIONS DURATION AGEjob.batch/helm-install-traefik Complete 1/1 30s 14mjob.batch/helm-install-traefik-crd Complete 1/1 28s 14m
kubectl create deployment nginx --image=nginx
kubectl expose deployment nginx --port=80 --type=LoadBalancer
kubectl get deployment
kubectl get pods
kubectl get svc
NAME         TYPE        CLUSTER-IP   EXTERNAL-IP   PORT(S)   AGE
kubernetes   ClusterIP   10.43.0.1    <none>        443/TCP   17m
helm
curl https://raw.githubusercontent.com/helm/helm/main/scripts/get-helm-3 | bash
helm repo add prometheus-community https://prometheus-community.github.io/helm-charts
helm repo add grafana https://grafana.github.io/helm-charts
helm repo update
helm install prometheus prometheus-community/kube-prometheus-stack
helm install grafana grafana/grafana
"grafana" has been added to your repositoriesHang tight while we grab the latest from your chart repositories......Successfully got an update from the "grafana" chart repositoryUpdate Complete. ⎈Happy Helming!⎈NAME: grafanaLAST DEPLOYED: Wed Sep 23 16:42:00 2026NAMESPACE: defaultSTATUS: deployedREVISION: 1NOTES:1. Get your 'admin' user password by running:kubectl get secret --namespace default grafana -o jsonpath="{.data.admin-password}" | base64 --decode ; echo2. The Grafana server can be accessed via port 80 on the following DNS name from within your cluster:grafana.default.svc.cluster.localGet the Grafana URL to visit by running these commands in the same shell:export POD_NAME=$(kubectl get pods --namespace default -l "app.kubernetes.io/name=grafana,app.kubernetes.io/instance=grafana" -o jsonpath="{.items[0].metadata.name}")kubectl --namespace default port-forward $POD_NAME 30003. Login with the password from step 1 and the username: admin####################################################################################### WARNING: Persistence is disabled!!! You will lose your data when ########### the Grafana pod is terminated. ######################################################################################
testing
model suggestion
For a local, heterogeneous environment (ARM, AMD, NVIDIA), avoid vanilla Kubernetes. Use a lightweight distribution to match your “simple configuration” requirement.
- Distribution: Use K3s (single binary, ARM-native) or Kind. K3s supports device plugins for NVIDIA (Jetson) and AMD (ROCm) GPUs out of the box.
Permissions (Fixing Host Access): Instead of the
usermodworkaround in the Dockerfile, use HostPath volumes restricted by RBAC.;; hostPath allows editing without root inside the podvolumeMounts:- name: workspacemountPath: /app/codevolumes:- name: workspacehostPath:path: /home/youruser/projectsConfigure the Pod Security Context to allow the specific node user (matching
ubuntu) to access the path without full root access.- GPU Integration: Deploy the
nvidia-device-plugin(for NVIDIA) or equivalent for AMD to dynamically allocate GPU resources to the LLM pods. - Services:
- Ingress: Use nginx to expose the LLM and API endpoints securely.
- Storage: Keep models in
ConfigMapsor localPVCsfor portability. Keep source code inhostPathfor speed.
- Migration: Convert
docker-compose.ymlto Helm Charts or Kustomize to manage the stack declaratively.
This setup reduces context (as desired for security) while maintaining the flexibility of containerization on ARM/AI hardware.
Write here in org-mode the snippet to create the k3s configuration suggested above:
Installation
# Install K3s (works on ARM, AMD, NVIDIA)
curl -sfL https://get.k3s.io | sudo INSTALL_MODE=1 sh -
# Configure GPU support in containerd (requires NVIDIA container runtime)
# Add to /etc/k3s/agent.env for worker nodes
# K3S_EXEC="--node-label gpu=true --node-role=worker"
- Server Configuration (k3s.yaml)
# This is for the server startup args, usually passed to the server process
# server:
#   service-port: 6443
#   agent-port: 10000
#   cluster-init: false
#   token: "mytoken"
#   data-store-endpoint: /var/lib/rancher/k3s/server/db
#   disable:
#     traefik: false  # Only if you handle ingress manually
#
# To enable GPU support at runtime, ensure the 'nvidia-container-toolkit'
# is installed on the host and the runtime is set in containerd.
- Deployment (Ollama + HostPath)
#+BEGIN_EXAMPLE
This deployment addresses the permission issue:
1. Uses ’hostPath’ to access the code without root inside the pod.
2. Matches host user/group via ’securityContext’.
apiVersion: apps/v1
kind: Deployment
metadata:
  name: ollama
spec:
  selector:
    matchLabels:
      app: ollama
  template:
    metadata:
      labels:
        app: ollama
    spec:
      # Use host PID for better file permissions
      containers:
        - name: ollama
          image: ollama/ollama
          ports:
            - containerPort: 11434
          volumeMounts:
            - name: models
              mountPath: /root/.ollama
            - name: code
              mountPath: /app
          # Request GPU if present
          resources:
            limits:
              nvidia.com/gpu: 1
      volumes:
        # Access host directory (must be writable by the UID)
        - name: code
          hostPath:
            path: /home/youruser/projects/source
            type: DirectoryOrCreate
        - name: models
          hostPath:
            path: /home/youruser/.ollama
            type: DirectoryOrCreate
#+END_EXAMPLE
- Note on Permissions
;; Ensure K3s containerd respects the host user for file operations
;; Edit /etc/containerd/config.toml
[plugins."io.containerd.grpc.v1.cri".containerd.runtimes.runc.options]
  SystemdCgroup = true
- Prerequisites
This setup assumes a K3s server is installed. Replace the command in the DaemonSet with the correct K3s command if not running via script.
- Configuration Files
k3s_server.yaml
# Install K3s on server
curl -sfL https://get.k3s.io | INSTALL_K3S_VERSION=v1.29.0+ex1.sh
ollama_service.yaml
This defines the LLM service with hostPath for source editing.
apiVersion: apps/v1
kind: Deployment
metadata:
  name: ollama
  namespace: llm
spec:
  replicas: 1
  selector:
    matchLabels:
      app: ollama
  template:
    metadata:
      labels:
        app: ollama
    spec:
      containers:
        - name: ollama
          image: ollama/ollama:latest
          command:
            - ollama
            - serve
          ports:
            - containerPort: 11434
          securityContext:
            runAsUser: 1000  # Match host UID
            fsGroup: 1000     # Match host GID for hostPath
          volumeMounts:
            - name: models
              mountPath: /root/.ollama
            - name: workspace
              mountPath: /workspace
      volumes:
        - name: models
          hostPath:
            path: /root/.ollama
            type: DirectoryOrCreate
        - name: workspace
          hostPath:
            path: ~/projects/spiega  # Adjust to your host path
            type: DirectoryOrCreate
nvidia_gpu.yaml
apiVersion: v1
kind: Namespace
metadata:
  name: llm
---
apiVersion: apps/v1
kind: DaemonSet
metadata:
  name: nvidia-device-plugin
  namespace: kube-system
  labels:
    app: nvidia-device-plugin
spec:
  selector:
    matchLabels:
      app: nvidia-device-plugin
  template:
    metadata:
      labels:
        app: nvidia-device-plugin
    spec:
      serviceAccountName: nvidia-device-plugin
      containers:
        - name: device-plugin
          image: nvidia/k8s-device-plugin:1.0
          volumeMounts:
            - name: nvidia-device-plugin-socket
              mountPath: /var/run/nvidia-device-plugin.sock
              name: nvidia-device-plugin-socket
      volumes:
        - name: nvidia-device-plugin-socket
          hostPath:
            path: /var/run/nvidia-device-plugin.sock
- Usage
- Apply the server config (already run).
Apply GPU support:
kubectl apply -f k3s/gpu-daemonset.yamlApply LLM service:
kubectl apply -f k3s/ollama-deploy.yamlPort Forward for access:
kubectl port-forward svc/ollama 11434:11434 -n llm- Edit source directly on host, accessible via mounted volume at
/workspaceinside the pod.